
When I watch an AI agent spend four minutes crawling a Figma file to answer a question I already knew the answer to, I get impatient. I get frustrated. Not because I’d memorized it — because the answer is computable. The agent was reading 45 variants, one by one, not even trying to infer which properties change across states. C’mon isn’t even an inference problem! It should be a diff!
To date we’ve worked like this: an engineer is assigned a component, opens a connection to a Figma file, pokes around, learns structure, infers decisions, and writes code. MCP is genuinely useful and fits this workflow well. It’s human-paced exploration now with an AI turboboost.
Yet, design system teams face two kinds of decisions. The hard kind — which components belong in the library, how to structure variant hierarchies, polishing up design intent, when to compose versus configure — require judgment, context, and experience. Our workflows necessarily involve inspection and reflection, inference and decision making. MCP tools help with that. Crafting code from Figma’s (partial) rendering of our intent can be similarly nuanced, and there are moments MCP can help there too.
But that moment in between – what we’ve called “handoff” that extracts a Button’s anatomy from 45 variants, diffs states, resolves token references — has no ambiguity at all. It’s mechanical, known, deterministic. The answers are in the data. And today’s agents seem happy to dawdle and lollygag around all that data over and over over, tokens be damned.
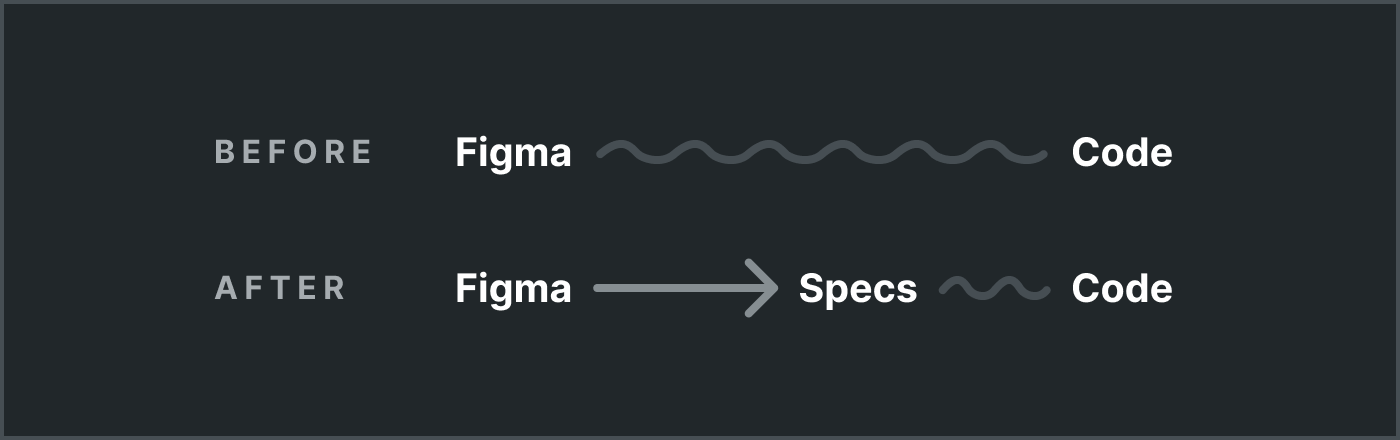
I see teams shaping a different model for tomorrow. Coding agents take a spec and generate types, structure, styling, behaviors, and accessibility in parallel, governed by rules and skills. Humans review this at gates rather than doing discovery themselves. As components change, the work is knowing what’s different and changing just that. That pipeline needs a pre-computed, durable, and comparable artifact.
I built a tool to generate specs mechanically, and design systems of enterprise scale are using this as a primary Figma-to-code input to agentically generate code. Sure, making decisions downstream remains the hard part. But extracting complete and compact specs from Figma should be a blazingly fast, repeatable activity. This post describes the problems I see, how to think mechanically about specs, the command line tool I built that my teams use, and examples of why it matters.
The Problem:
Raw Figma Data Is the Wrong Starting Point
However you get it — MCP, REST API, plugin — raw Figma data has limitations when thrown to AI to generate components at scale.
Figma data is expensive and ephemeral
MCP fetches and processes vast payloads every time, throwing countless tokens to take it through its paces. Nothing persists. The work is disposable. The chat ends, the data dies, the memory largely flushed as attention diverts elsewhere.
Figma data is a noisy dumping ground
Data isn’t incomplete, it’s overloaded. 26,901 properties when you need ~350. Signal-to-noise ratio is abysmal. Plus, you get 45 full variant copies when what matters is 15 subtle differences between them, organized by simple rules that trigger each.
Figma data isn’t clean
Even library files have inconsistent naming, orphaned variants, dead variables, and experimental components mixed in. It’s messy in there. But that’s the job of the systems designer to clean that up, and MCP tools help to clean that up. It’s just that handoff isn’t the time to expose that. Just because we are using AI doesn’t mean letting our guard down.
Figma data is unprocessed
The raw data speaks Figma’s language: opaque IDs (5641:6912), float RGBA wrapped in solids, gradients and effects when a style already mapped to your design token will do. Hash-suffixed property names (Label#3813:0) when a prop binding reference can be set cleanly.
Figma favors Figma
Figma’s data model is Figma’s, not your platform’s. Figma says paddingLeft — but iOS needs .padding(.leading) and CSS needs padding-inline-start. Figma treats an icon glyph as a nested component instance, while code typically references SVG assets you color. Figma lacks a native model for ARIA roles and screen reader labels, but your components ship with each. A cross-platform spec needs to be neutral ground, not one tool’s more limited view. Your pipeline speaks token references using your formats, clean prop names, semantic anatomy.
Something somewhere has to translate. AI should be reading, not writing, these specs from Figma. As it turns out, all this requires is a scriptable algorithm.
The Right Tool for the Job:
Mechanical Transformation
Figma’s data model is stable, incomplete and evolving slowly. Surely you’ll have “unstructured” and “less structured” specs to describe behaviors, motion, accessibility and more. But what it does cover, it covers cleanly.
Therefore, you can build tools to derive rules-based decisions from variant data using a dependable and durable algorithm. I want my design intent in an artifact that’s:
complete, such that every property of every layer of every variant is examined meticulously and every decision that matters is recorded
compact, compressing data from MB to KB to remove 99% of the noise
precise, with differences across variants reduced to simple, layered rules
translated into a more platform-neutral language and using token, data, and file formats that work for you
versioned so that as you evolve, it detects what’s changed since last time
human-readable, that designers can scan and see intent, details and mistakes
Specs must yield the same output given the same input, every time deterministically. This class of problem demands speed, not inference and improvisation. Never rely on a predictive model when you can count something directly. At this step in the process, you can count everything. If you can transform what is known faster, completely, precisely and far more compactly, then computation should win. Every time.
specs-cli:
Commands To Generate Your Specs For You
The specs-cli available at https://github.com/DirectedEdges/specs requires four terminal commands. The two main commands – fetch and generate run cleanly and quickly in ~30 seconds per library each time you need specs. The other two are one-time setup tasks that take a few minutes and are covered in getting started docs — or you can paste a single line into Claude Code and let Claude walk you through it.
## Install from npm
npm install -g @directededges/specs-cli
## Initialize and configure an environment (~1-2 min, one time)
specs init
## Fetch the Figma library file (5-15 seconds)
specs fetch
## Find and select components to generate (~1-2 min, one time)
specs scan
## Generates specs for an entire library file (10-30 seconds)
specs generate
In a few minutes, you have an entire, well-organized, compact specification of all the relevant design decisions you’ve put into an entire library. Need to refresh library data? Run fetch then generate again in less than a minute. Need to compare it against the last run? Ask AI, use Git to discern your changelog, or wait for tools I intend to build soon. Want to run it every week, day or hour using a Github action? Sure, however often you want.
Could AI do all this for you? Sure, but it’d take so so much longer, require so many tokens, and probably hallucinate in ways you can’t detect. Why do that?
Examples: A Disabled Button and Action List with Subcomponents
The proof? Imagine a button with 45 variations, 9 of which are disabled. The raw Figma data is 1.38MB large, 42,000+ lines of JSON comprising 280 nodes and their 26,000+ properties.
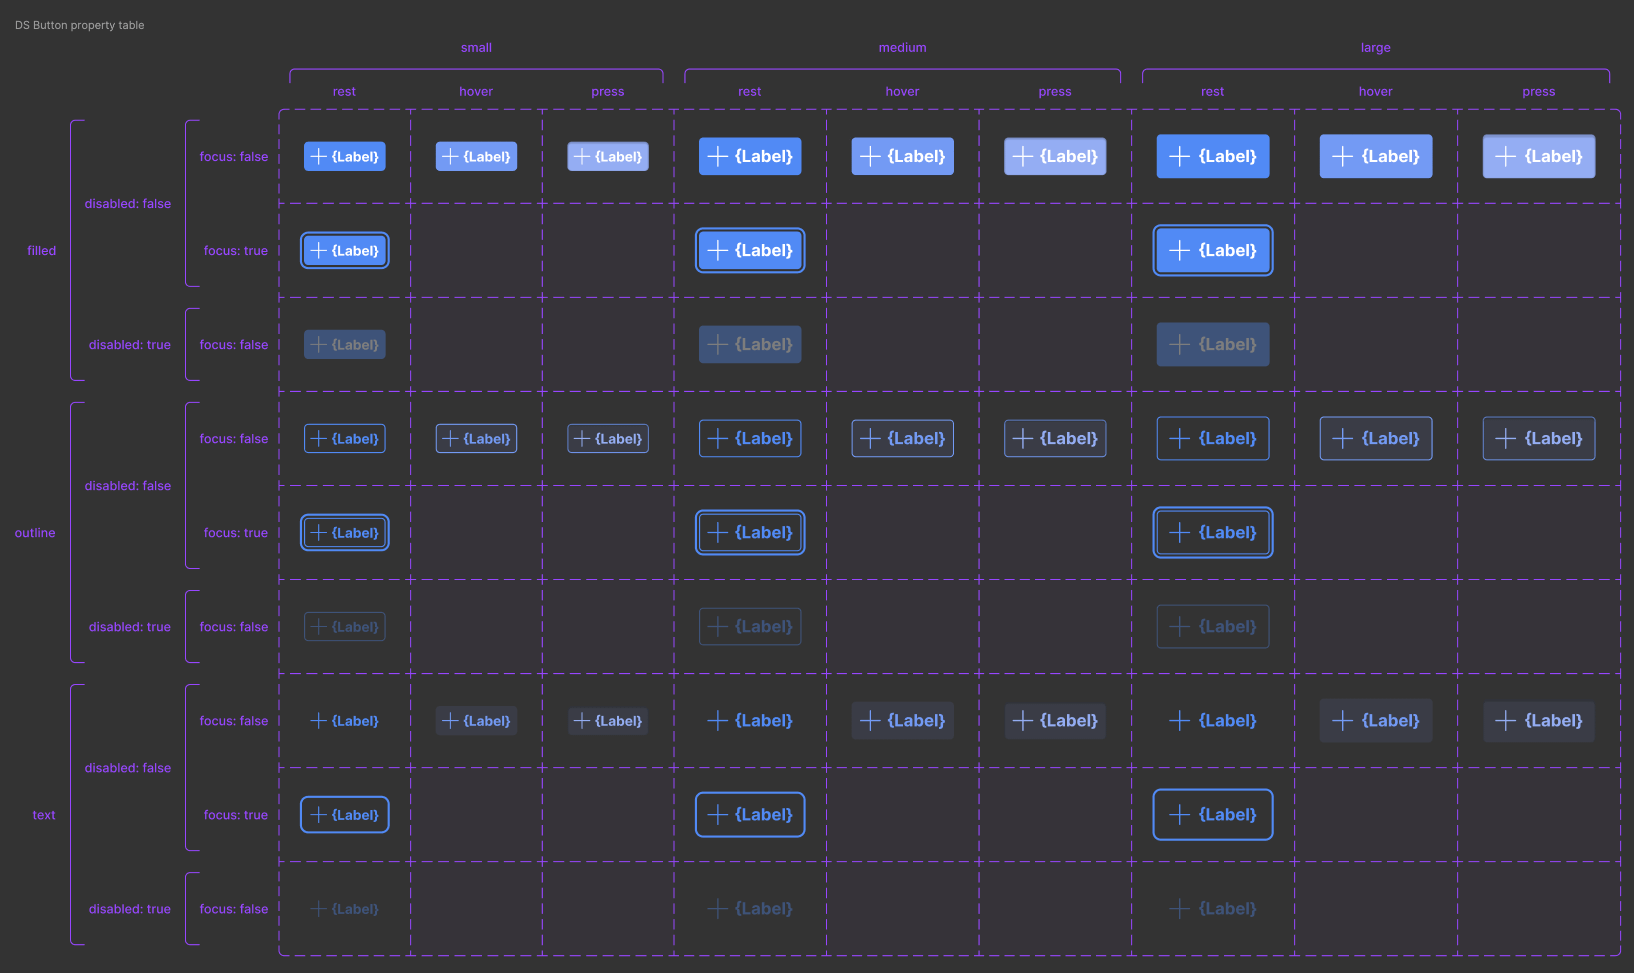
Process this with the specs-cli, and in about 1 second, and you are left with 10 KB, 442 lines, 4 anatomy elements and 15 configurations that yield rules with design decisions. It’s 99.25% less data, 134:1 compression into a well-organized schema.
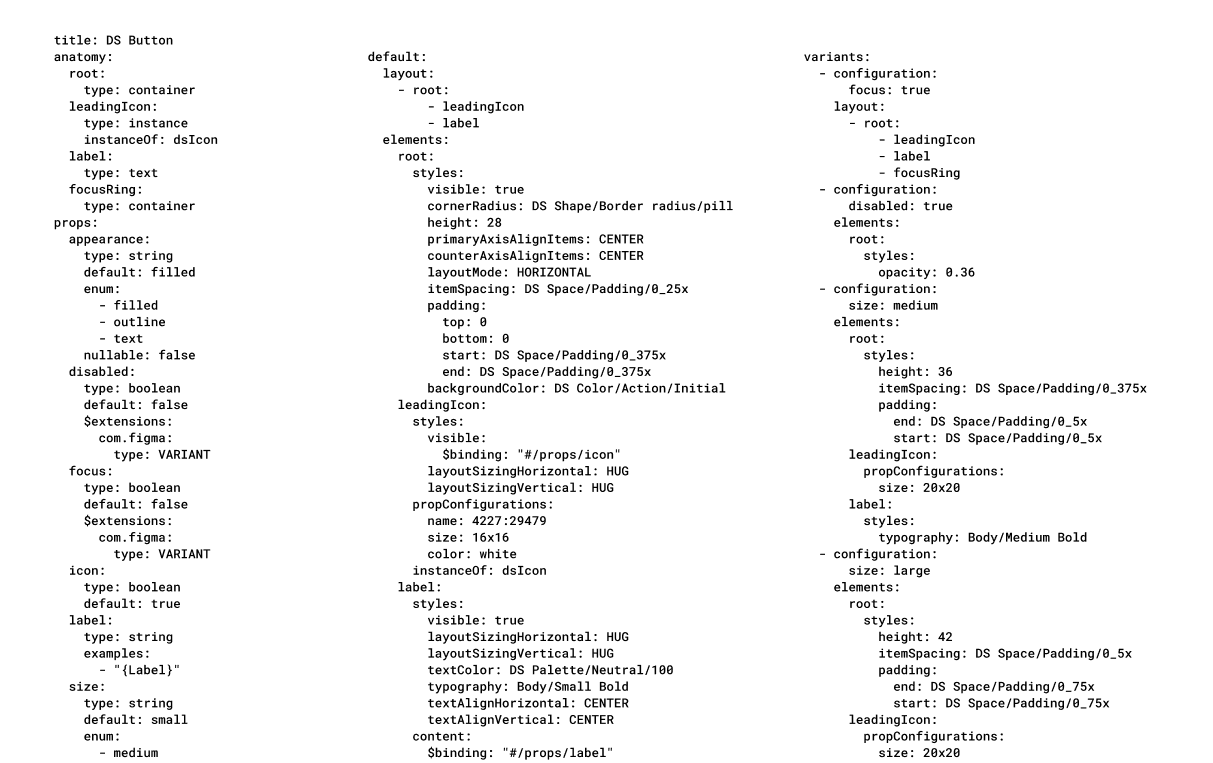
That spec is semantic anatomy, clean prop names, token references, diff-based variants, invalid variant analysis, structured metadata, and platform-neutral directions. Along the way, it discards bounding boxes, transforms, geometry paths, opaque IDs, duplicate variant copies, paint object wrappers, useless and exceedingly redundant information.
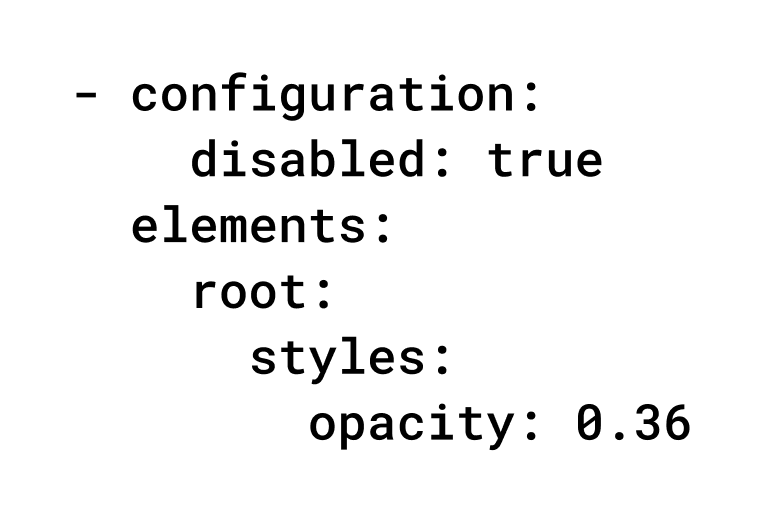
AI doesn’t need 80 nodes with 30+ properties each when your design intent is “When the button is disabled, make the root layer 0.36 opacity.” A simple rule will suffice. And humans can read it too. Not that designers want to spend their time reading YAML. Yet, acclimating to the structure and scanning it quickly can yield small corrections to unexpected misses that polish the delivery.
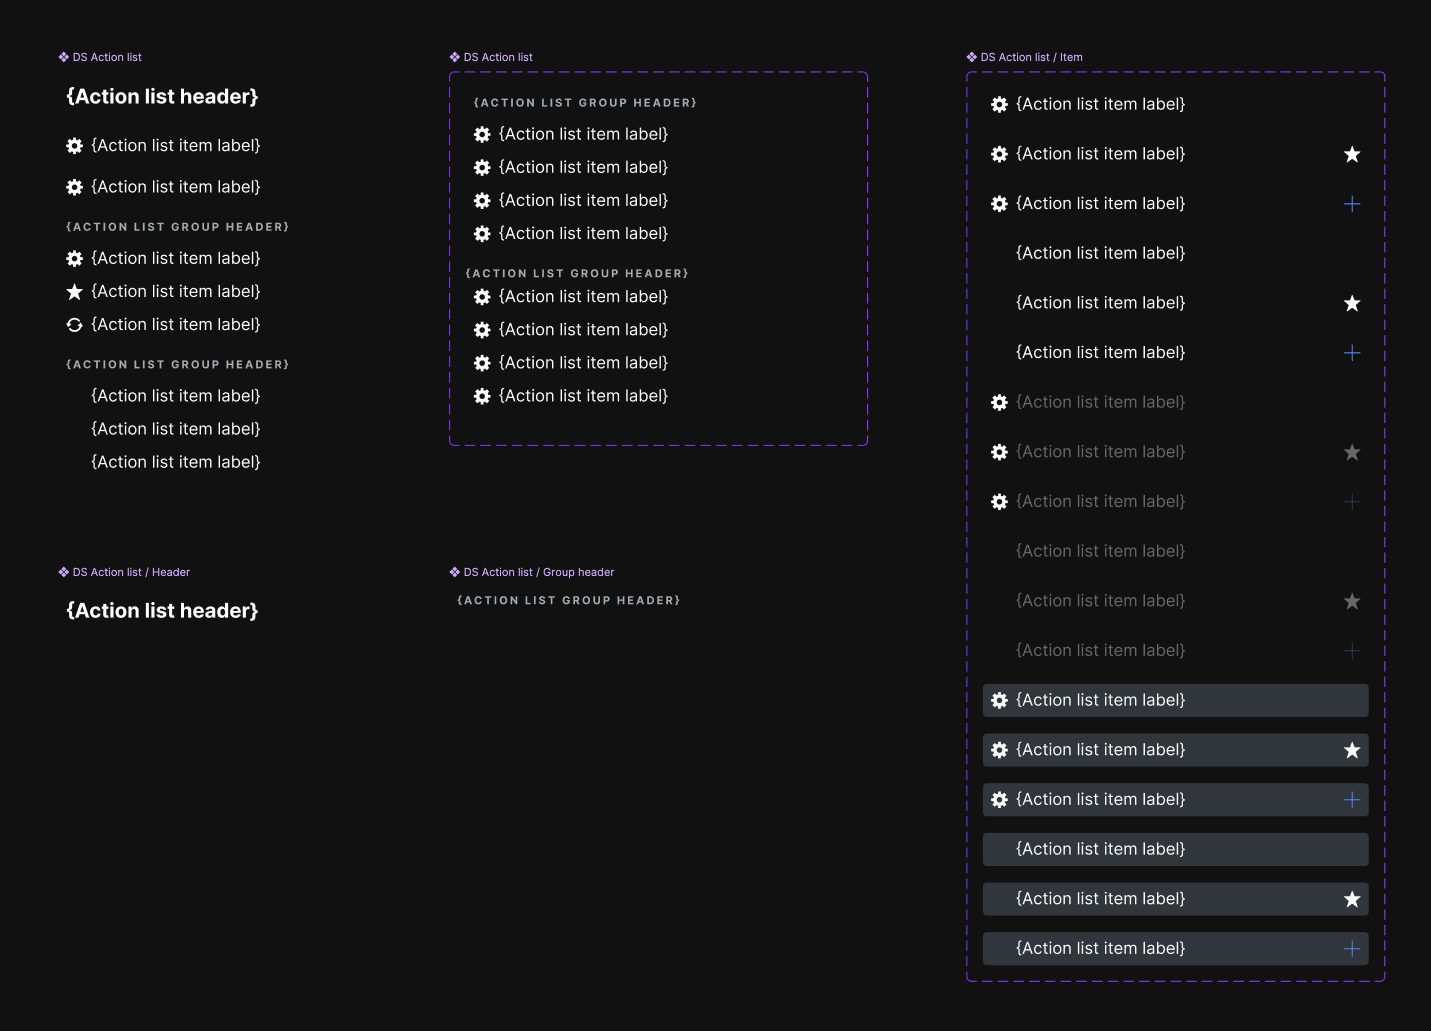
Do you think the Button example flatters this approach, but remain unconvinced? More complicated components with a bevy of subcomponents result in **even more** compression. The Action List, with its subcomponents for items, headers, groups and group headers, resulted in a 2.6MB → 14KB (188:1 compression, 99.47% reduction), and yet included even more that Figma doesn’t like conditional visibility, code only props and invalid combination mappings.
Where was AI this time? At most, running your commands, although you can do this without AI and use zero tokens. AI belongs in this pipeline: *downstream*, not necessarily to generate specs. A mechanical engine can produces a durable, precise artifact; AI agents can consume it to generate code, answer questions, build components.
Extending and Moving Beyond Components
There are clear places where the specs tools will need to grow in the short term. Capturing slot content and instance examples is imminent. VPs are demanding refined motion and behaviors, yet nobody uses Figma for that. From there, questions about how to capture and relate deeper behavior (usually reserved for code) and accessibility persist.
At the same time, the tools are already in use at clients, and more than one see git versioning as insufficient. I would anticipate building in versioning capabilities that include automated changesets, changelogs and classification of major, minor and patch changes.
Leadership, however, has already moved their attention to other things. Components seem like well understood territory, but AI’s pattern recognition and speed of automation has them clearly desiring to go up the chain to layout patterns, scaffolds, and full page compositions. Not just what they are but also when to use and relate and compose each one. I cannot imagine how fast these things will change or look in months let alone years.