
For years, we’ve toiled to maximize design system quality through collaboration from design through handoff to production. Today, our processes are boosted with AI, with component design intent hopping back and forth between codebases, LLM chats and design tools.
Through this period, our systems must improve how we get design intent out of (and back into) design tools as a part of a system’s broader pipeline. Not just efficiently, but precisely. Not just to vibe, but to record and version. Not just for us, but them (cough cough, AI) too.
If we are to use components as data, how do we do it without losing or degrading it as data shifts back and forth across our tools? We need a model to describe components, and tools to transform and move that description.
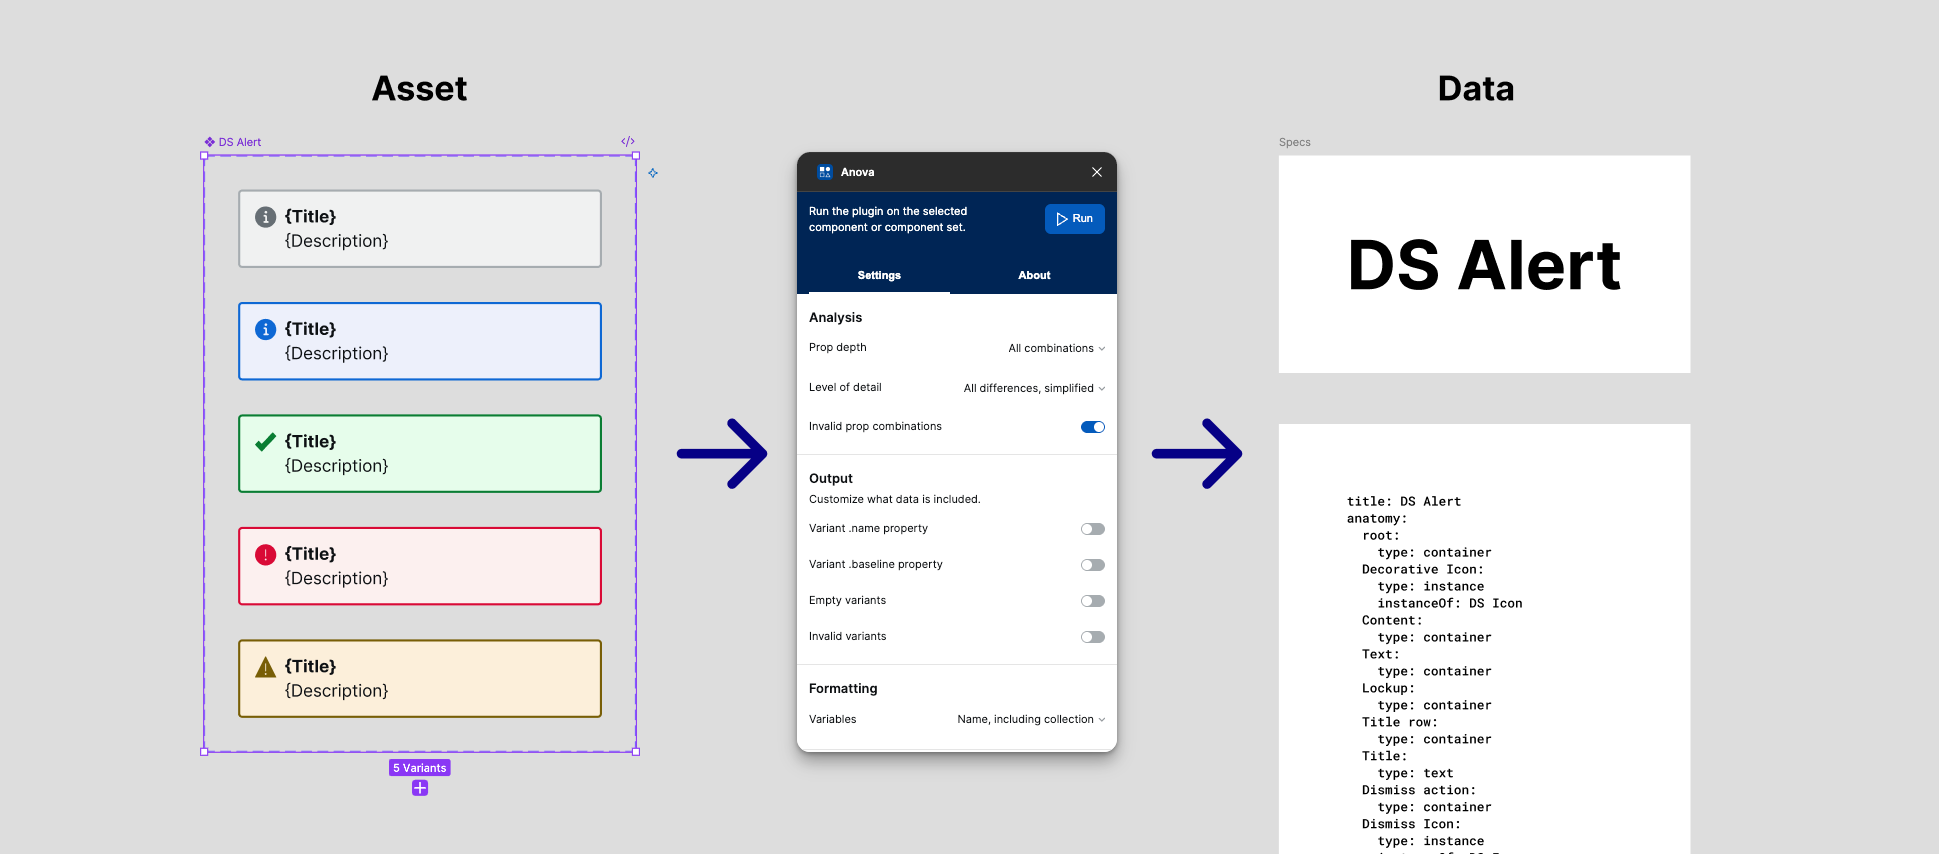
The Anova plugin, recently released in the Figma community, could be a part of that process. Built as a second generation the Specs plugin engine, the plugin produces component data with a more refined and extensible model. This post describes the plugin’s intent to output components as data, the data model it follows, and key principles that drove it’s conception and shape.
About the Anova plugin
The Anova plugin creates a component specification in data form. In particular, the plugin conducts an “analysis of variants” to audit component composition, visual styling, and prop configurations across all variants.
The plugin name alludes to traditional statistical analysis of variance, and is a hat tip to my college education. Yet the plugin isn’t actually doing statistical analysis. Instead, it crawls a Figma asset to produce a result that’s deterministic, repeatable, succinct and comprehensive. This output unlocks myriad opportunities for design system pros, as described in Components as Data:
Leverage component definitions in AI LLMs
Version component definitions over time
Analyze components across a catalog
Inspect component precision and quality
Handoff design to development
Generate documentation
Automate precise Figma asset generation (aka, the “round trip”)
Modeling the data
The Anova plugin’s engine is a more polished and better built second generation of the Specs plugin, which launched in 2023 and has output similar if less refined data for over a year.
The model of the plugin’s data output conforms to an available JSON schema and can be formatted as YAML or JSON. The data includes things you expect from a spec: an anatomy of elements, props and an analysis of how structure, styles and configurations shift by variant. It also hints at things you wouldn’t expect too, like a summary of invalid variants combinations.
Anatomy
The anatomy data includes a straightforward list of elements by type as well as growing metadata (such as component dependencies).
anatomy:
  root:
    type: container
  label:
    type: text
  icon:
    type: instance
    instanceOf: DS Icon
Props
The props section summarizes properties including type, enums, defaults and other relevant prop information.
props:
  label:
    type: string
    default: "{Label}"
  appearance:
    type: string
    default: critical
    enum:
      - critical
      - warning
      - success
      - info
  size:
    type: string
    default: large
    enum:
      - small
      - medium
      - large
Variant-by-variant analysis
The plugin evaluates a Figma asset a variant at a time. The plugin starts wih the default variant, identifying each element of the anatomy that is present from the root component layer down through the layer hierarchy to assess layer styles, layout structure and other properties.
default:
  elements:
    root:
      styles:
        fills: DS Color/Alert/Basic/Background filled
        cornerRadius: DS Shape/Border radius/Pill
        itemSpacing: DS Space/Item spacing/0_5x
        paddingLeft: DS Space/Padding/0_5x
        paddingRight: DS Space/Padding/0_5x
        paddingTop: DS Space/Padding/0_25x
        paddingBottom: DS Space/Padding/0_25x
    label:
      styles:
        fills: DS Color/Text/Primary
        textStyleId: Body/Large
      propReferences:
        characters:
          $ref: "#/props/Label"
From that established default, successive variants are evaluated, compared to other variants serving as baselines, and reduced into a succinct spec across all variants.
variants:
  - configuration:
      size: small
    elements:
      root:
        styles:
          itemSpacing: DS Space/Item spacing/0_25x
          paddingLeft: DS Space/Padding/0_25x
          paddingRight: DS Space/Padding/0_25x
          paddingTop: DS Space/Padding/0_125x
          paddingBottom: DS Space/Padding/0_125x
      label:
        styles:
          textStyleId: Body/Small
  - configuration:
      appearance: success
    elements:
      root:
        styles:
          fills: DS Color/Alert/Success/Element
      label:
        styles:
          fills: DS Color/Text/Primary Inverse
From the resulting variants data, you can layers styles and other data based on one or more matched configurations in a manner very similar to CSS’ cascade.
For example, if this component was configured as both size:small and type:success, then the data would layer in three matches (the default then matches for size and type) to resolve as:
elements:
  root:
    styles:
      fills: DS Color/Alert/Success/Element
      cornerRadius: DS Shape/Border radius/Pill
      itemSpacing: DS Space/Item spacing/0_25x
      paddingLeft: DS Space/Padding/0_25x
      paddingRight: DS Space/Padding/0_25x
      paddingTop: DS Space/Padding/0_125x
      paddingBottom: DS Space/Padding/0_125x
  label:
    styles:
      fills: DS Color/Text/Primary Inverse
      textStyleId: Body/Small
Invalid variant combinations
The invalidVariantCombinations section summarizes prop combinations that are invalid based on the Figma asset. For example, an interactive component typically cannot be disabled and hover at the same time. Depending on how you’ve built your component in Figma, those combinations can be determined and summarized.
invalidConfigurations:
  - disabled: true
    state: hover
  - disabled: true
    state: active
  - disabled: true
    focused: true
Principles
Extensibility, interoperability, validation, and portability are table stakes for any data structure. On top of that, four more principles drove decisions: determinism, completeness, succinctness, and human-readability.
✅ Deterministic instead of stochastic
The problem: Data extracted from Figma’s Dev Mode MCP Server is impressive, but isn’t designed to produce a durable spec unless your spec is a React and Tailwind implementation. The extracted data, transformed further via LLMs, yields unpredictable results: sometimes imprecise, often incomplete, and frustratingly different run to run.
For example, I’ve observed an LLM starting with an Alert component’s appearance:success|critical|warning|info property behaving unpredictably. Over repeated runs, it renamed options (information), added options (neutral), remove options (warning) and renamed the property itself (to type or variant)! A design system can’t rely on an unstable workflow for a canonical component description.
props:
  appearance:
    type: string
    default: critical
    enum:
      - critical
      - warning
      - success
      - info
The plugin’s approach: The plugin extracts only the raw, intentional data directly from the asset. No guessing. No machine prediction. The same input yields the same output, every time. And each time, it’s easy to compare it to past versions to affirm and commit to the differences. You designed it to be appearance:success|critical|warning|info, so you get appearance:success|critical|warning|info.
✅ Complete instead of partial
The problem: The data derived from Specs Figma plugin ouptut is powerful. People upload screenshots of it to LLMs and it kinda works! However, it evaluates prop effects in isolation. It doesn’t inspect every variant in depth to find every potential effect on style and structure.
For example, it’s easier to document a component’s background color when hover:true or selected:true. How about when both are true? How about when both are true, and the component is also set to appearance:info? Did the component change more? These interactions are rare and harder to analyze, but they shouldn’t be missed by a shallow analysis.
variants:
  - configuration:
      hover: true
    elements:
      root:
        styles:
          backgroundColor: (a color)
  - configuration:
      hover: true
      selected: true
    elements:
      root:
        styles:
          backgroundColor: (a second color)
  - configuration:
      hover: true
      selected: true
      appearance: info
    elements:
      root:
        styles:
          backgroundColor: (a third color)
The plugin’s approach: The plugin can inspect every variant in-depth and then reduce what’s accumulated into a set of matches that layer into a rendered style. Instead of disjointed snapshots relying on one prop, you get the entire picture no matter the (valid) prop combination.
✅ Succinct instead of bloated
The problem: Figma provides access to a complete picture of component assets via its REST API. Unfortunately, its variant architecture is very bloated. To express a disabled:true state for a component like Text Input, could mean 24 more variants each with ~15 layers per variant each with ~40 properties.
Ask Figma’s REST API for component information, and you’ll get 14,400 additional properties in hierarchical data! 99.99% of that data tells you nothing new, but it needs to be processed and examined to make sure. All because a designer expressed a simple intent of “When disabled, set the root layer’s opacity to 0.36.”
variants:
  - configuration:
      disabled: true
    elements:
      root:
        styles:
          opacity: 0.36
The plugin’s approach: Instead of duplicating entire variants, it records only the difference: what changes when disabled. That’s compact, lossless, and easier to maintain.
✅ Human-readable instead of gobbledygook
The problem: Even if you get deterministic and complete data, it’s usually encoded in ways that only a machine can love — long and noisy JSON dumps with no obvious hierarchy of what matters.
title: {component name}
anatomy:
  {element name}:
     type: {type}
     instanceOf: {main component name}
  ...
props:
  {prop name}:
     type: {type}
     default: {default}
  ...
default:
  elements:
    {element name}:
       styles:
         {style name}: {value}
variants:
  - configuration:
      {prop name}: {value}
    elements:
      {element name}:
        styles:
          {style name}: {value}
The plugin’s approach: Outputs are structured so a human can scan them. Defaults come first. Overrides are grouped by condition. Names are consistent. Reading the data feels like reading a spec.
I’ll acknowledge right now that designers aren’t in love with reading a spec as data. It does require onboarding (a few good docs rich with examples seem to be enough). Yet, I’ve been pleasantly surprised at how quickly specs-as-data sprout up next to assets. It’s value becomes even clearer when Figma comments start showing up above the spec rather than asset to get things done.
Ideally, if Anova data proves valuable to the community, the plugin could go in many directions. At the forefront, I’d expect to integrate this new processing engine into the Specs plugin (or vice versa, overlaying the spec outputs onto Anova) in the future, consolidating the two.
I also can’t imagine this living long without strong, direct integration with other tools. This suggests that MCP server and/or Figma REST API integration could prove useful directions to pursue. Yet, for now, it’s certainly useful enough to share, get feedback, and grow.